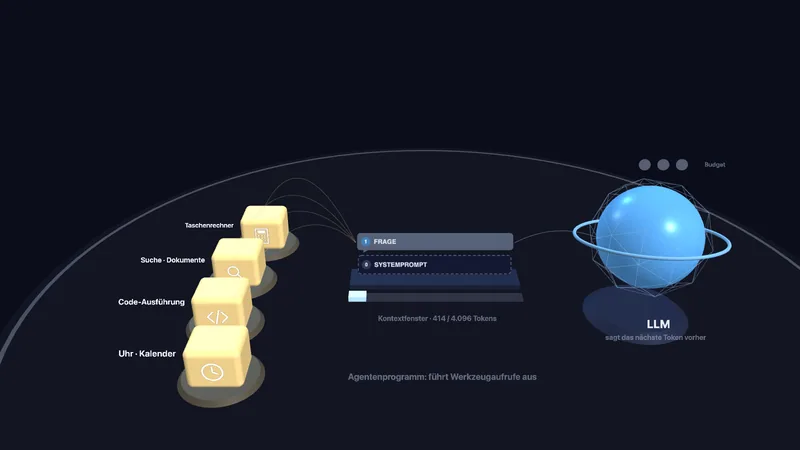
Agent loop
An LLM agent is a loop: the model writes tool calls as text, a program executes them and every observation grows into the context — with and without tools compared, including a tool failure and a prompt injection.
Neural networksTry itVisuApps
Interactive visualisations of neural networks and deep learning
Apps
An LLM agent is a loop: the model writes tool calls as text, a program executes them and every observation grows into the context — with and without tools compared, including a tool failure and a prompt injection.
Neural networksTry it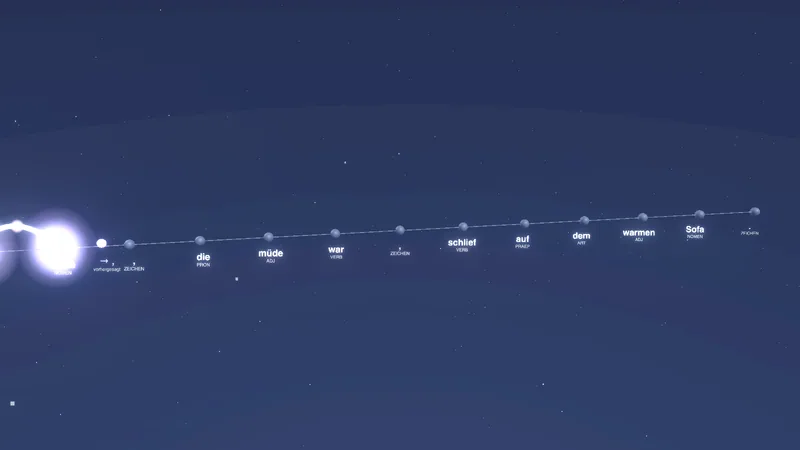
Self-attention made visible: query, keys, softmax(QKᵀ/√d)·V, five specialised heads, a matrix heat map with causal mask, a second layer and a by-hand calculation with three tokens.
Neural networksTry it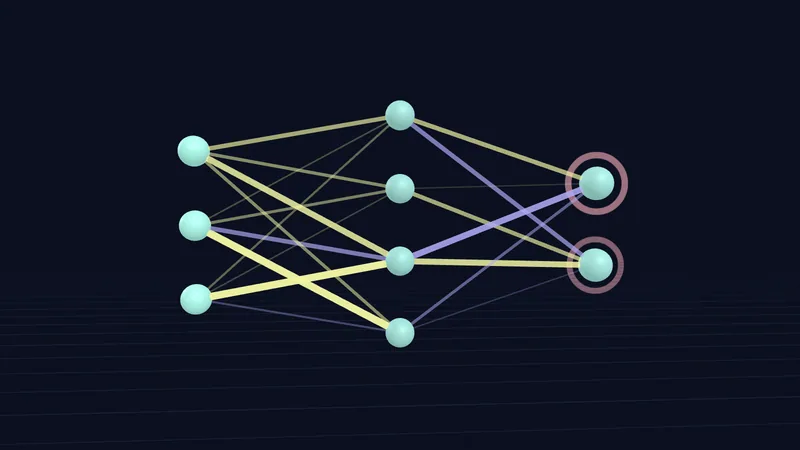
Backpropagation on a 2-2-2 network with real numbers in six steps: forward pass, loss, δ at the output and in the hidden layer, gradient per weight, only the update lowers the loss — checked numerically.
Neural networksTry it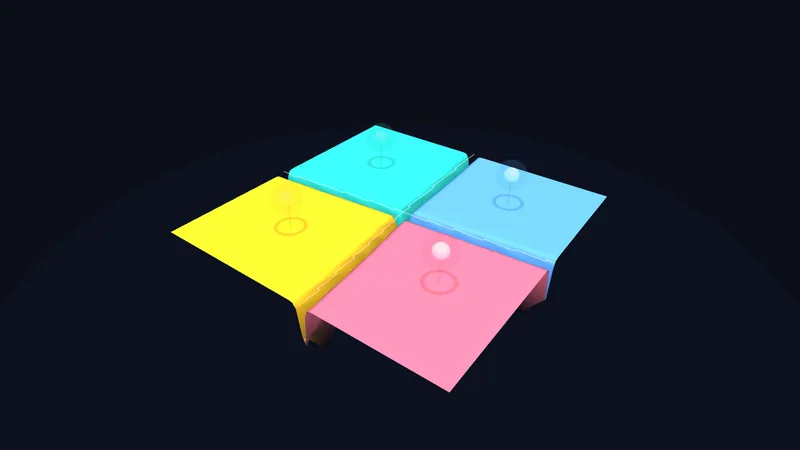
Drag target points across a plane while a neural network colours the basins of attraction live. The "network size" slider: too few neurons → coarse, wrong basins — the "enough neurons?" question to touch.
Neural networksTry it
Explore 20 occupations as task cubes with ILO exposure scores — and discover why exposure is not a job-loss forecast.
Neural networksTry it
Logits become a distribution via softmax(z/T): temperature, greedy, sampling, top-k and top-p with a visible cut-off line, entropy, a decision tree of the generation and loops at T = 0.
Neural networksTry it
Thousands of particles flow step by step from Gaussian noise into shapes: forward and reverse process, DDPM vs. DDIM and classifier-free guidance. An image panel shows the same in pixel space, coarse shape first and details last.
Neural networksTry it
Words as vectors in a space of meaning: similarity as cosine in the full space, analogy arrows, neighbours and three 3D shadows (map, PCA, axes) with how much neighbourhood each one keeps.
Neural networksTry it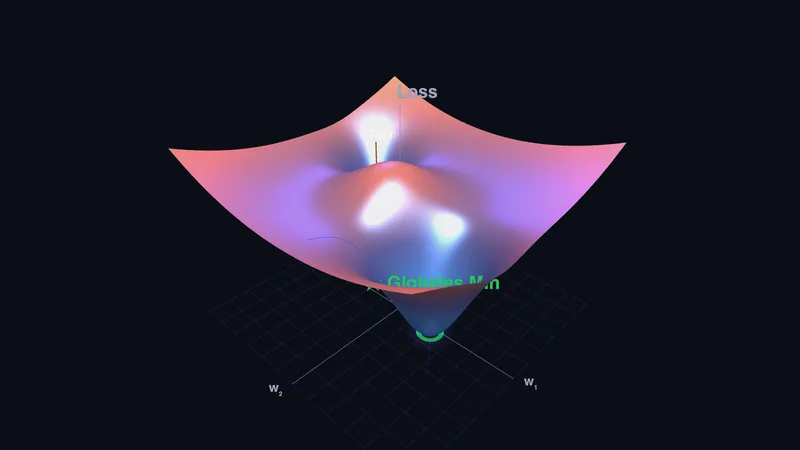
Loss surface of a real line fit in 3D: θ ← θ − η∇L with stability limit 2/λmax, two valleys and a saddle, GD, momentum and Adam racing, SGD noise and the fitted line in the model panel.
Neural networksTry it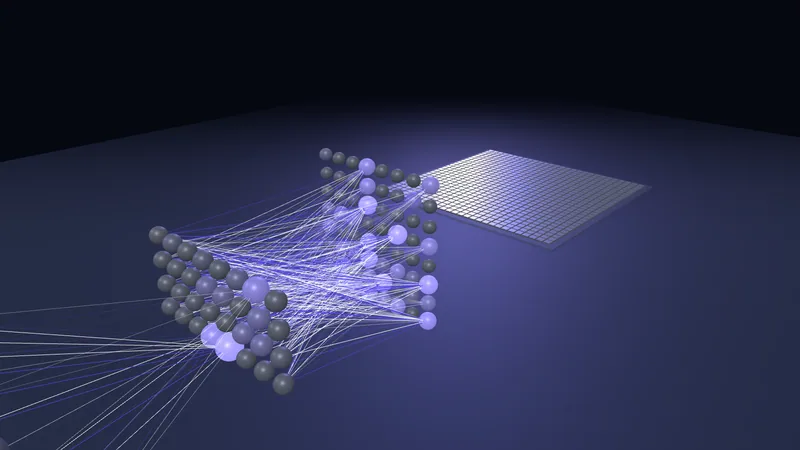
A drawn digit flows through a real network trained on MNIST (784 → 64 → 32 → 10): weight images per neuron, forward wave, softmax bars and test digits it gets confidently wrong.
Neural networksTry it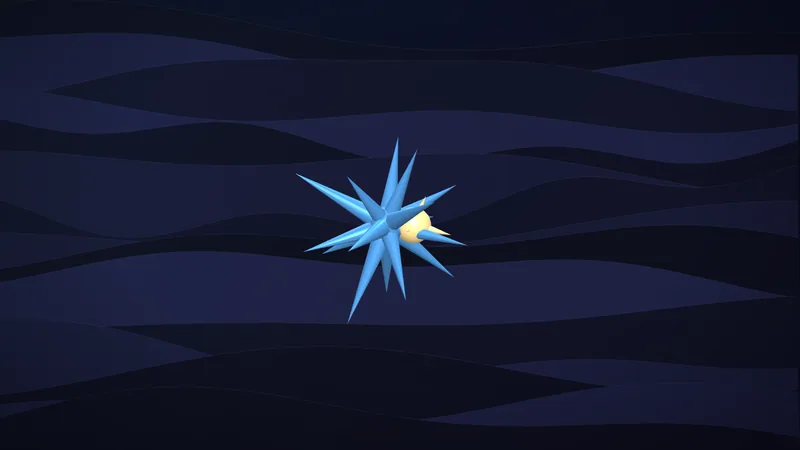
Two 3D stars — human and AI: each spike is a task domain, its length the capability level. The AI grows extremely unevenly (code and proofs explode, physical common sense lags); slid together the stars interpenetrate — there is no single overtaking moment (after Karpathy).
Neural networksTry it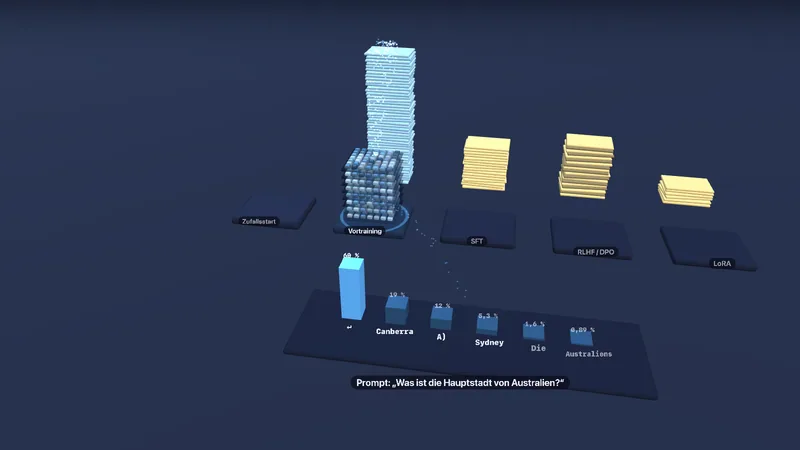
The same prompt through pretraining, SFT, RLHF/DPO and LoRA: the knowledge comes from pretraining, the later stages mainly shift which answer is likely.
Neural networksTry it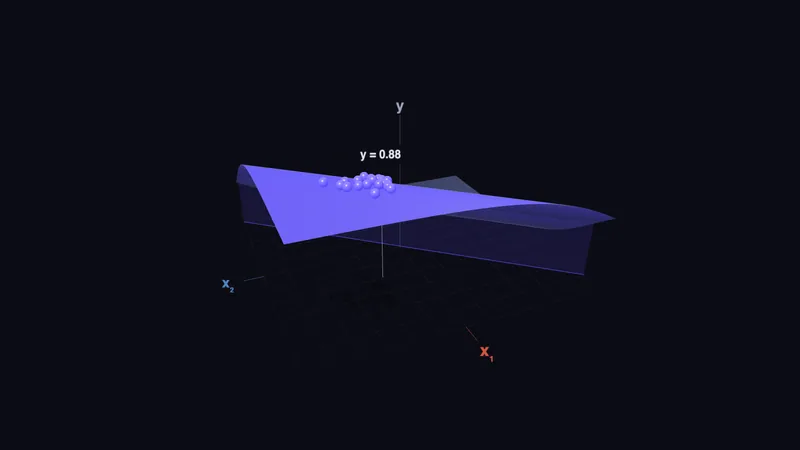
One artificial neuron: weighted sum, activation, a decision line in the input plane with the w arrow and bias offset; perceptron rule and gradient step solve AND and OR, XOR stays at 75 %.
Neural networksTry it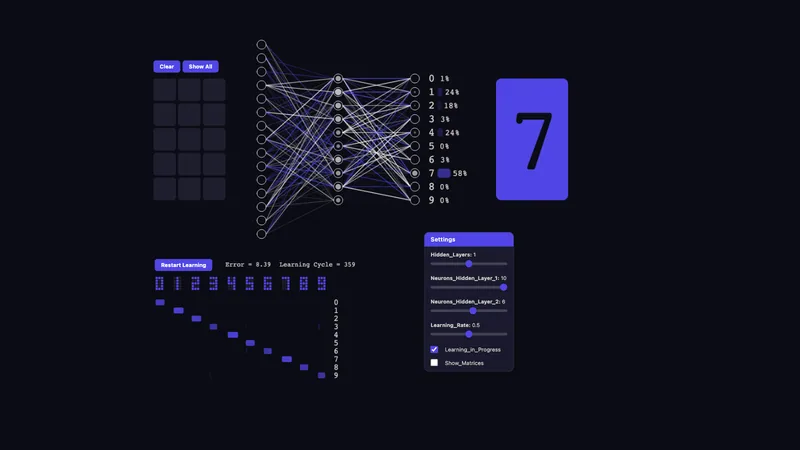
A neural network as a function: every neuron visible, ReLU kinks as building blocks of the output, weights editable per neuron, parameter count; curve, plane and digits modes.
Neural networksTry it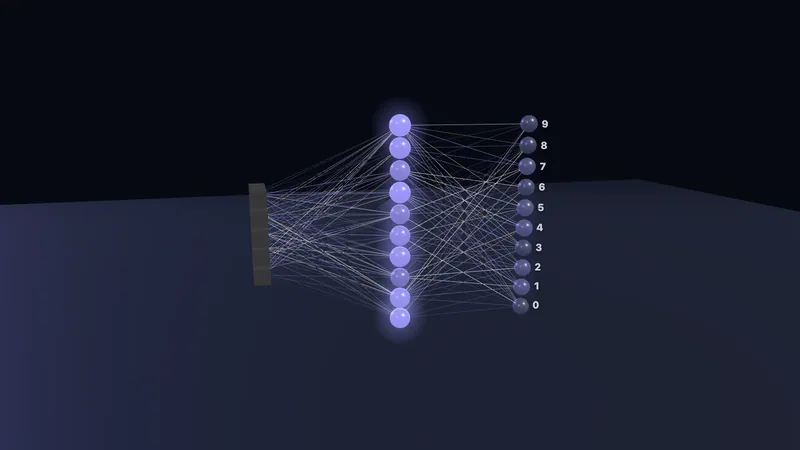
Training lab for neural networks in 3D: neurons as tiles showing their output, edges by weight, spiral, XOR, moons, layers, activations and regularisation live; plus a digits mode.
Neural networksTry it
Retrieval-augmented generation step by step: chunks, embeddings, search by cosine, BM25 or hybrid, top-k cut-off, prompt with token budget and an answer with sources; missed chunks lead to hallucination.
Neural networksTry it
You compare answers: a reward model learns from them (σ(r_A − r_B)), the policy shifts under a KL leash; with a loose leash the flattering answer wins (reward hacking); plus the DPO route.
Neural networksTry it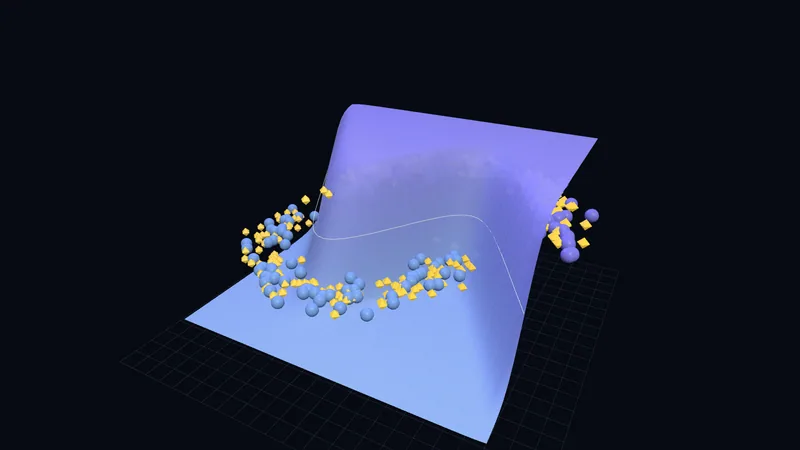
Reading training dynamics from the loss curves: learning rate, batch size, epochs, training and validation loss, early stopping at the validation minimum, L2, dropout, augmentation and more data against overfitting.
Neural networksTry it
GPT-2 runs in the browser — experience token generation, probabilities and architecture live.
Neural networksTry it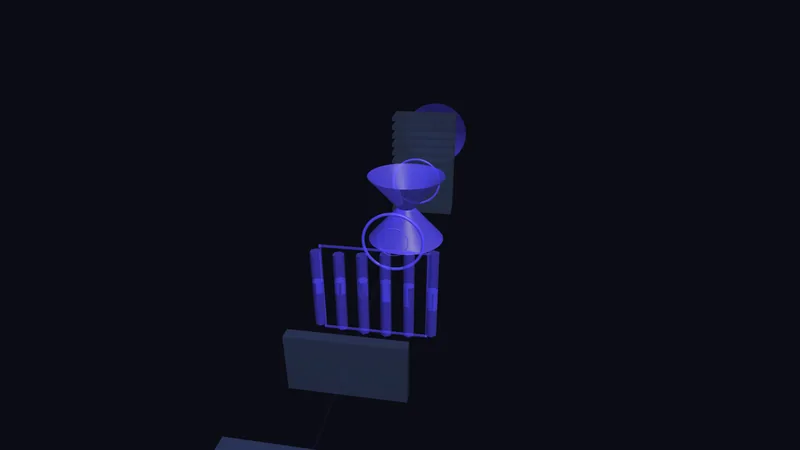
The GPT-2 architecture to walk through: residual stream through 12 blocks, masked attention as bridges, MLP d → 4d → d, unembedding and softmax, one token at a time; parameters per component and GPT-3 for comparison.
Neural networksTry itWant to use these apps in your courses? Let’s find out what works for you.
One form, three matters. We answer personally.
We show heyprof on your own material. Tell us what you teach and we will prepare the conversation around it.